Search by meaning
Load the model once, embed your lines as documents and your search as a query, and score each line with a dot product.
use embed::{EmbedDevice, Embedder};
let lane = probe::probe_machine().filing;let device = EmbedDevice::try_from(lane).unwrap_or(EmbedDevice::Cpu);let mut embedder = Embedder::load("path/to/embeddinggemma-300m-q4", device)?;
let lines = [    "found a secret room behind the waterfall",    "the soundtrack in this level is incredible",];let docs = embedder.embed_documents(&lines)?;let query = embedder.embed_query("a hidden area")?;
let mut ranked: Vec<(f32, &str)> = docs    .iter()    .zip(lines)    .map(|(doc, line)| (query.iter().zip(doc).map(|(a, b)| a * b).sum(), line))    .collect();ranked.sort_by(|a, b| b.0.total_cmp(&a.0));
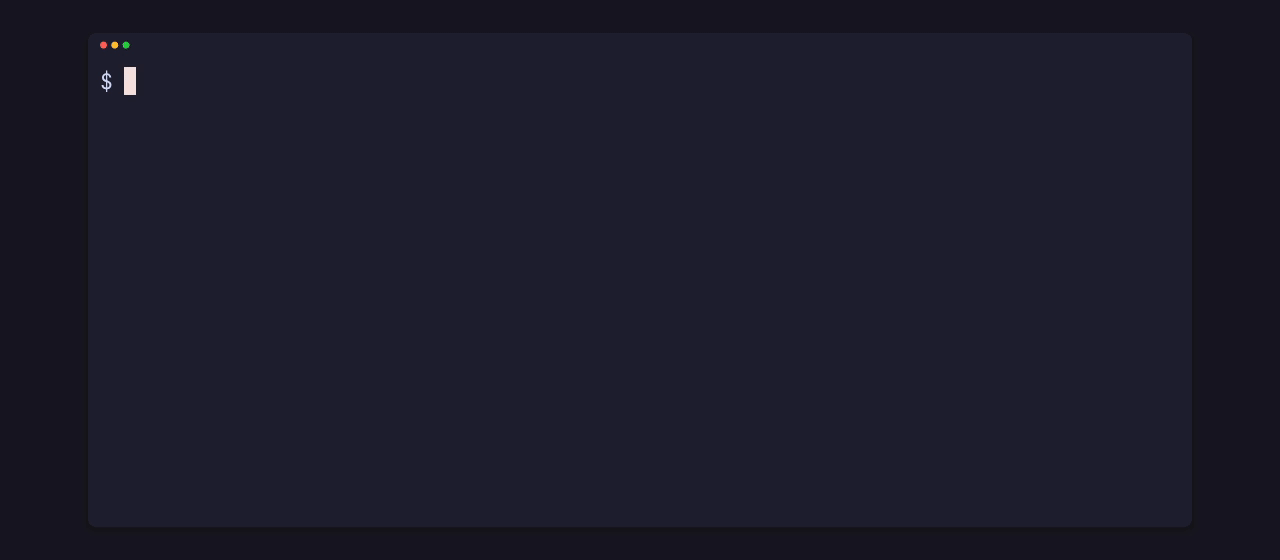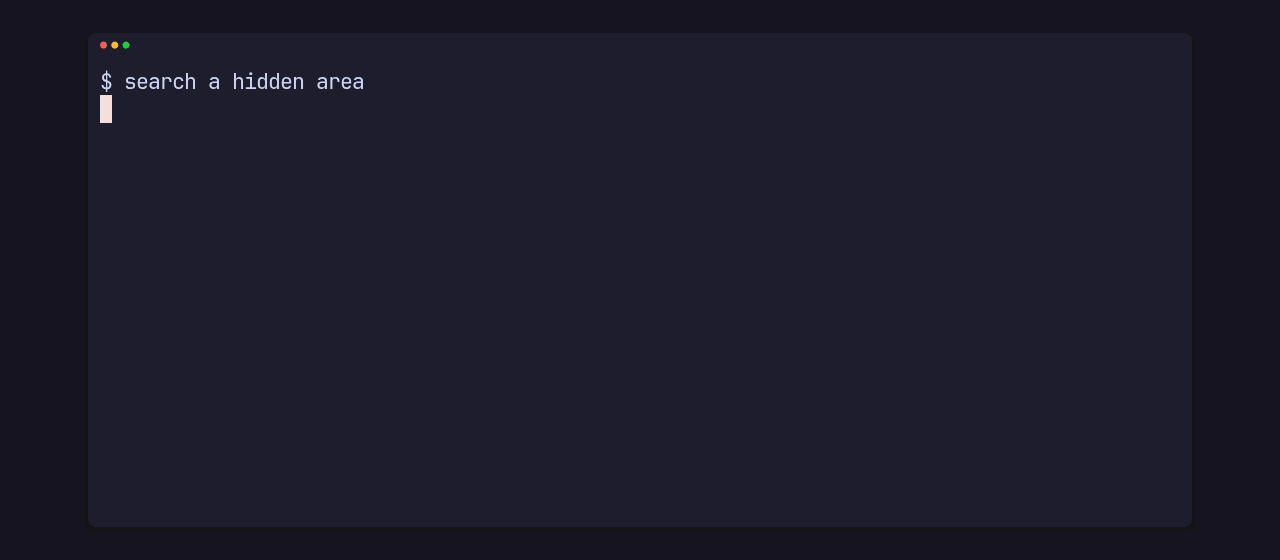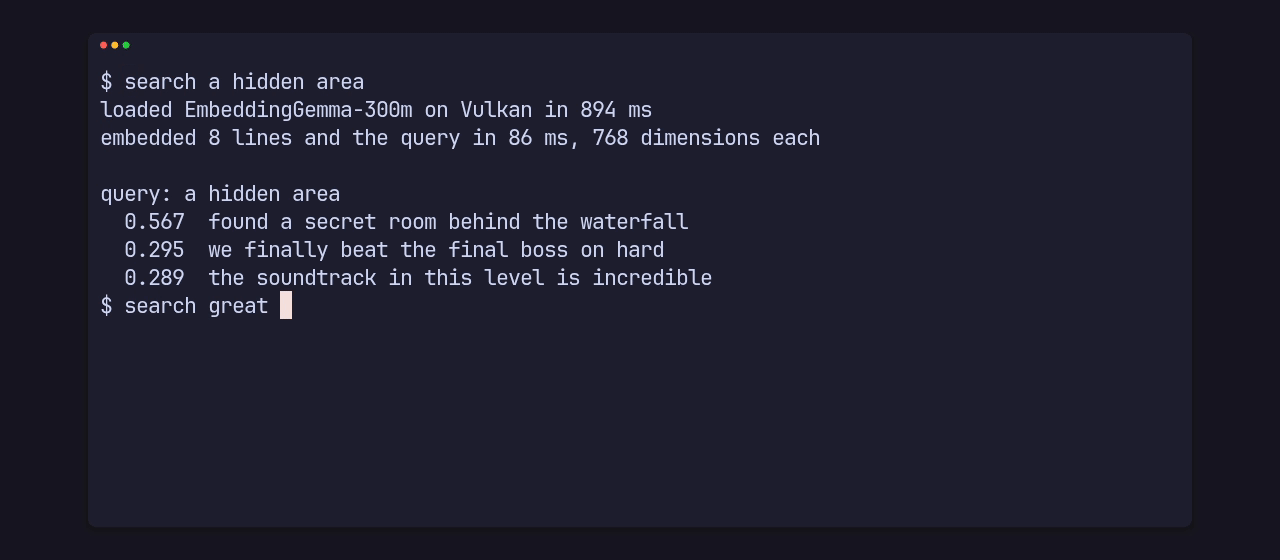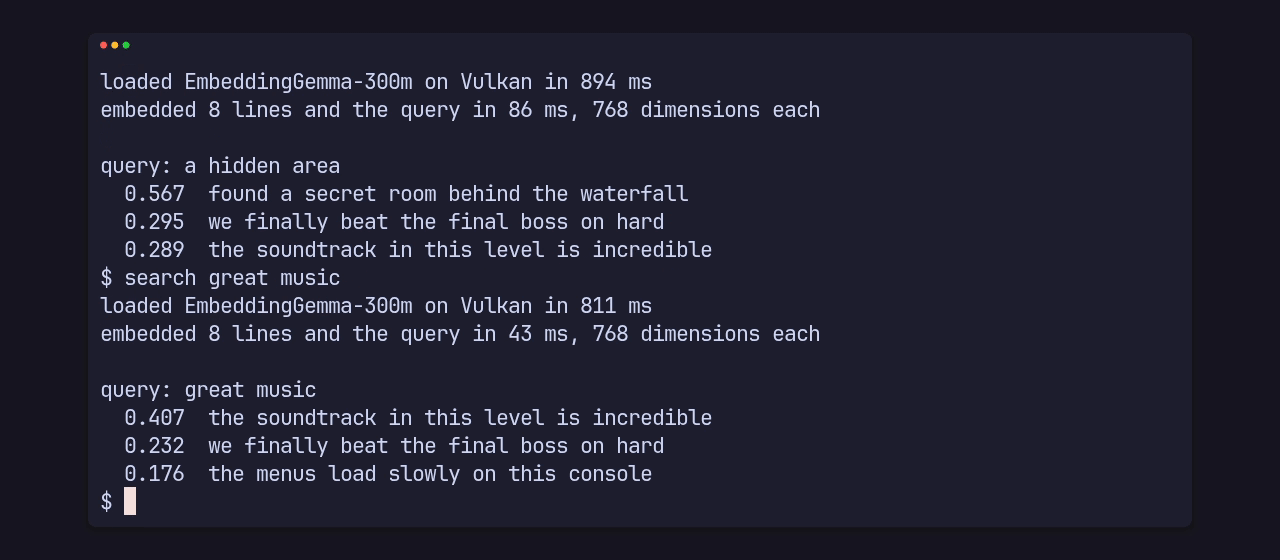
examples/search.rs in the repository is this, with eight lines and the model downloaded for you:
cargo run --release --example search -- great musicloaded EmbeddingGemma-300m on Vulkan in 1598 msembedded 8 lines and the query in 91 ms, 768 dimensions each
query: great music 0.407 the soundtrack in this level is incredible 0.232 we finally beat the final boss on hard 0.176 the menus load slowly on this console“great music” shares no word with “the soundtrack in this level is incredible”, and it still ranks first.
What the calls do
Section titled “What the calls do”embed_documents(&[&str])returns one vector per line, in order. An empty slice returns an empty list without touching the model. Pass many lines at once: batches are where the GPU pays (see Measure the speed).embed_query(&str)returns one vector.- Both apply EmbeddingGemma’s prompts for you:
title: none | text:before a document andtask: search result | query:before a query. Embed what you search withembed_queryand what you search through withembed_documents. - Every vector has
embed::DIMS(768) numbers and unit length, so the dot product of two vectors is their cosine similarity, from -1 to 1. Higher means closer in meaning. - Each line is cut at 128 tokens, about a long sentence; longer text is embedded from its first 128 tokens.
- Both take
&mut self. Keep oneEmbedderand reuse it: loading costs one to three seconds.
Errors
Section titled “Errors”Every call returns Result<_, EmbedError>:
| Variant | When |
|---|---|
ModelMissing { path } |
a model file isn’t in the folder; path names it |
GpuUnavailable { detail } |
the GPU can’t run the model; Embedder::load turns this into a CPU load on its own, see Pick a device |
LoadFailed { detail } |
ONNX Runtime refused the model |
Inference { detail } |
embedding a line failed |
The model folder is the subject of Get the model.