pito-embed
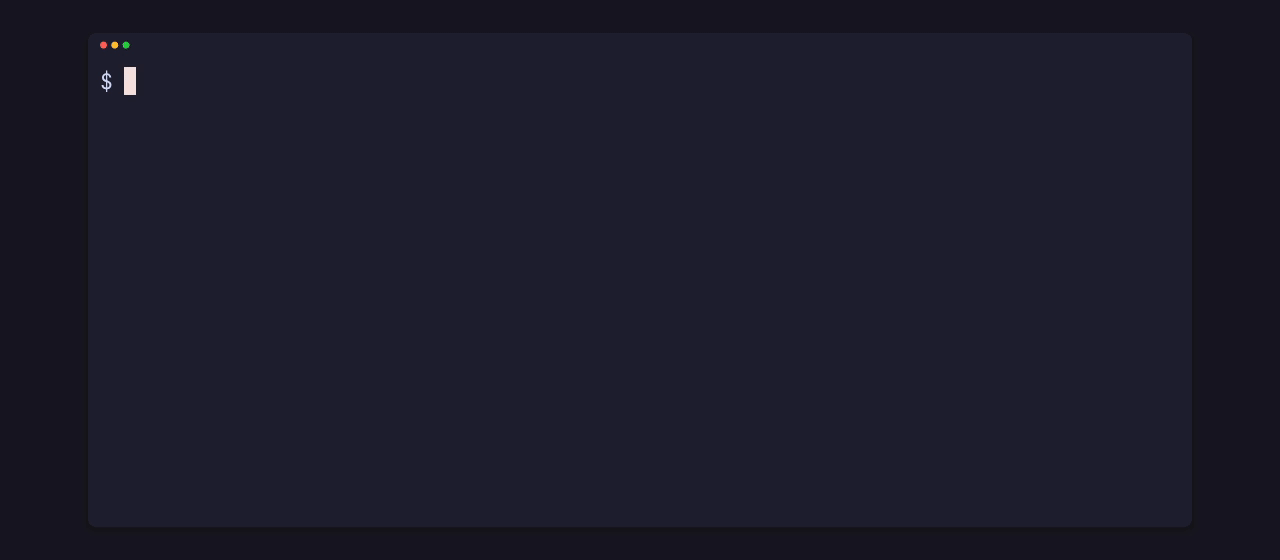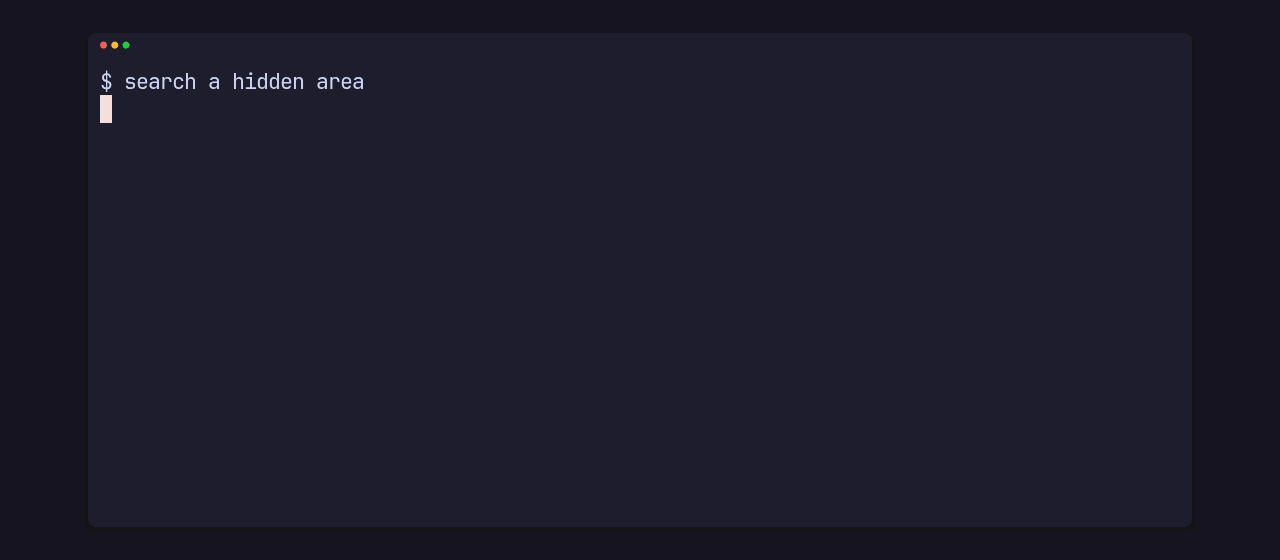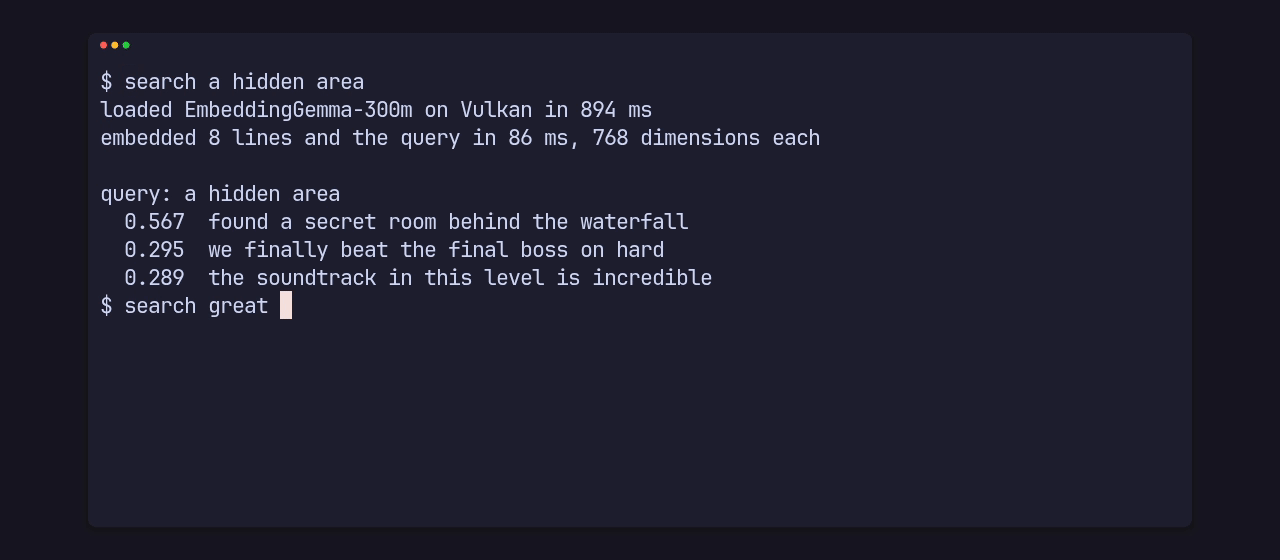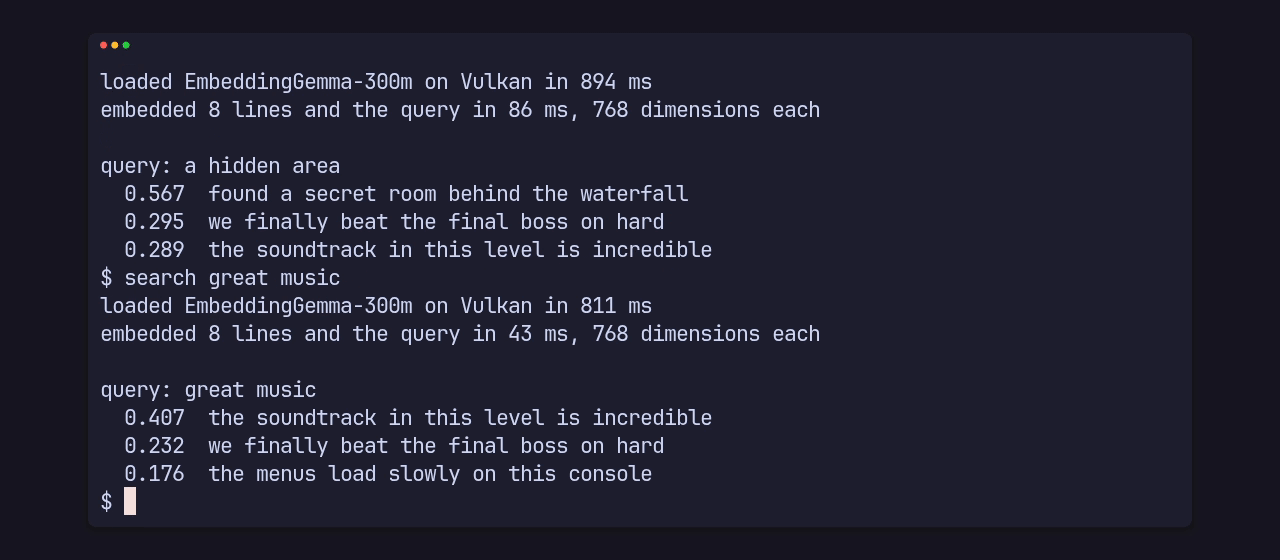
pito-embed turns text into embeddings on your own machine, in Rust: 768-number vectors where lines that mean the same thing sit close together, so you search by meaning instead of by words. It runs Google’s EmbeddingGemma-300m on the GPU when there is one and on the CPU otherwise, with no network at inference time.
It is two crates from one repository, pinned at one tag:
embedloads the model and turns lines into vectors.probereports the machine: the system, the graphics card and its memory, the best execution lane for each kind of work, every graphics adapter and the free disk space.embedreads it to pick a device.
The numbers
Section titled “The numbers”- 6.3× faster on the GPU: 256 lines embedded in 477 ms on Vulkan (536 lines a second) against 3,025 ms on the CPU, and one query in 17 ms against 29 ms. See Measure the speed for how.
- Three calls:
Embedder::load,embed_documents,embed_query. Vectors come back unit length, so a dot product is the cosine similarity. - Picks the device for you: if the GPU refuses the model, it runs on the CPU and tells you why.
- Offline and pinned: the model (219 MB, q4) is read from a folder you give it, every file pinned to one upstream commit and its sha256; the library never downloads anything itself.
- Small: 1,218 lines of Rust across the two crates, unit tests included; 5 direct dependencies for
embed, 3 forprobe.
Works on Linux and macOS (Windows through WSL).
Where to go next
Section titled “Where to go next”- Install and run the first search.
- Search by meaning: embed lines and a query and rank them.
- Get the model: download the pinned files and point the library at them.
- Pick a device: GPU or CPU, and what happens when the card refuses.
- Know the machine: what
probereports. - Measure the speed on your own machine.
- Ship a binary that embeds on the GPU.
- Formats: the vectors, the model folder and the catalog.
- The API reference for
embedandprobe, and the changelog.
The code is MIT licensed. EmbeddingGemma is Google’s model, under the Gemma Terms of Use; pito-embed ships no weights. The PITO MD name and its logos are © Catalin Ilinca, all rights reserved, and are not covered by the MIT licence.